Claude Haiku 5.5 costs 90% less for short prompts — use it as the cheap coding subagent, not the lead
Anthropic released Claude Haiku 5.5 on October 7, 2026. Its $0.10/$0.50 per-million-token short-prompt price and medium default effort make it a practical subagent for classification, repo triage, and compaction — but its coding benchmarks still sit below Sonnet 5.5.
Anthropic released Claude Haiku 5.5 on October 7, 2026. The API model ID is claude-haiku-5-5. Its useful builder story is not “replace your coding model”: it makes the cheap, frequent steps around a coding agent economical. (Source: Anthropic, 2026-10-07)
Key facts:
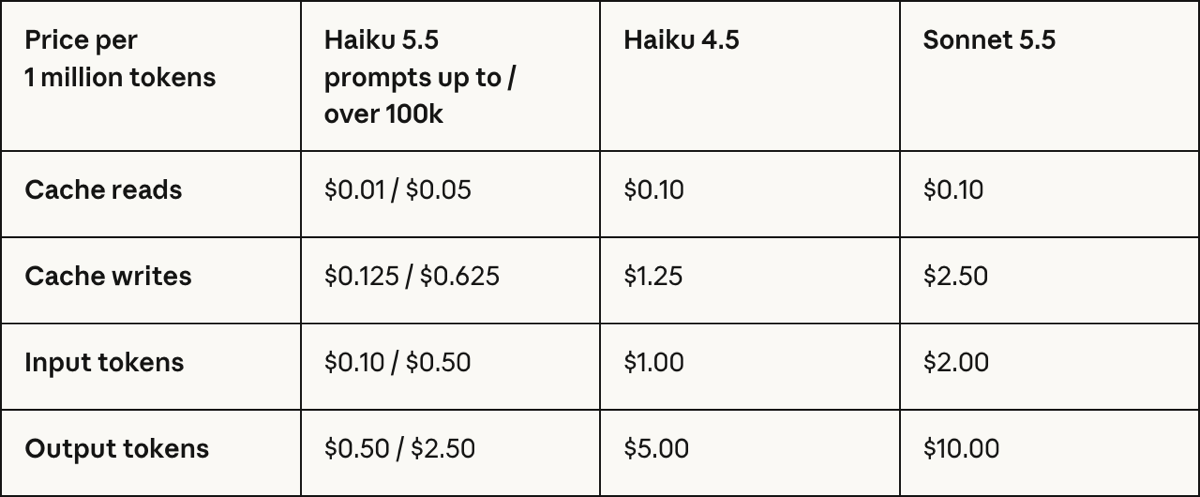
- Claude Haiku 5.5 costs $0.10 input and $0.50 output per million tokens for prompts up to 100,000 tokens.
- For prompts over 100,000 tokens, the rates are $0.50 input and $2.50 output per million tokens.
- The model has a 1M-token context window and a 128K-token maximum output.
- Its default effort is
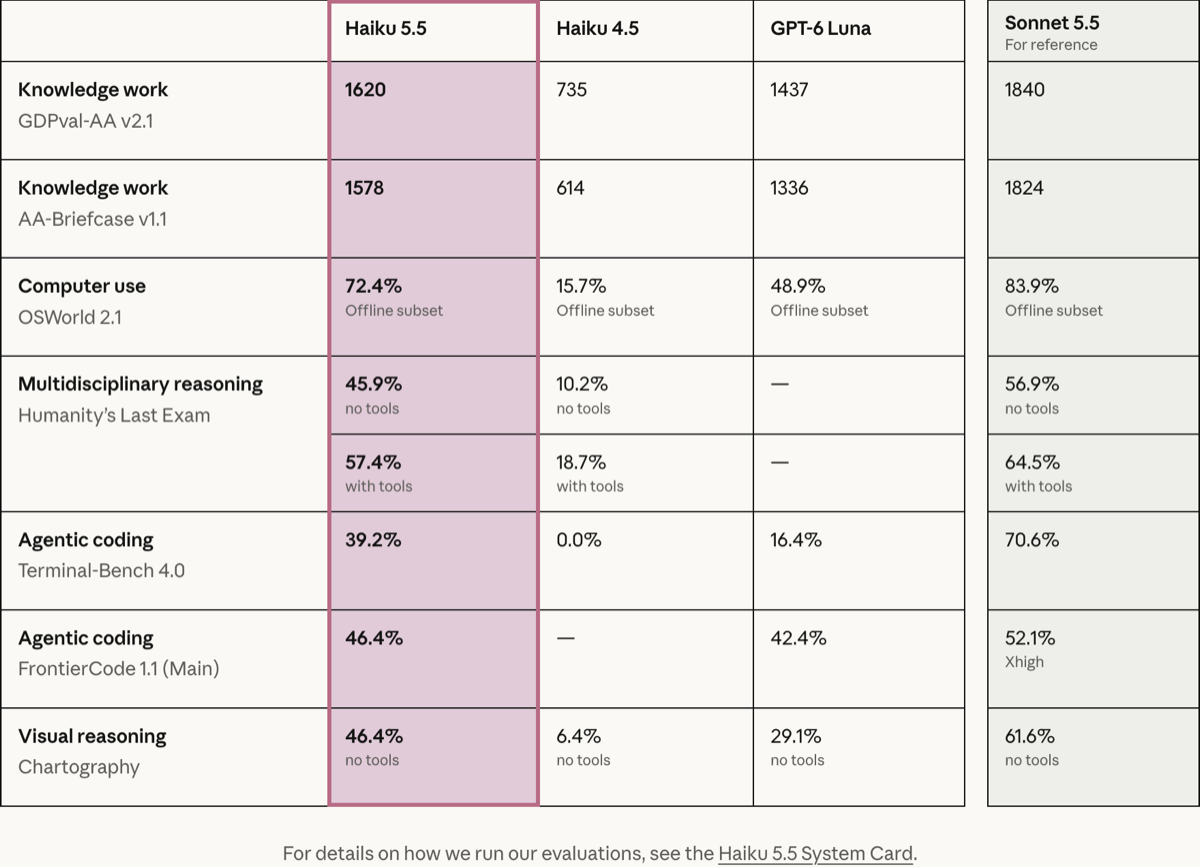
medium. - Anthropic reports 39.2% on Terminal-Bench 4.0, versus 70.6% for Sonnet 5.5 in the same launch table.
The route to change is the small work around the agent
For short prompts, Haiku 5.5’s input price is one tenth of Haiku 4.5’s $1.00 per million tokens, and its output price is one tenth of Haiku 4.5’s $5.00. (Source: Anthropic launch announcement, 2026-10-07)
That makes it a credible first-pass model for tasks that happen many times per coding job: classifying issues, extracting a reproduction recipe from logs, summarising a changed file, compacting agent history, or routing a request to a more capable model. Keep the lead implementation, debugging, and final review with Sonnet or Opus. Anthropic’s own comparison puts Haiku 5.5 at 39.2% on Terminal-Bench 4.0 while Sonnet 5.5 is 70.6%; those are vendor-reported benchmark results, not a promise about your repository. (Source: Anthropic, 2026-10-07)
The 100K-token boundary is a routing boundary
The price changes fivefold once a prompt exceeds 100,000 tokens. That means a “use Haiku for every long-context task” policy can erase much of the headline discount. Chunk a large repository scan into focused calls, pass only the relevant files, and reserve the full context for the agent that must reason over cross-file changes. (Source: Claude Haiku 5.5 model overview, retrieved 2026-10-10)
Haiku 5.5 supports adaptive thinking, text and image input, and tool use. It is available on the Claude API, Amazon Bedrock, Google Cloud, Microsoft Foundry, and Claude Platform on AWS. (Source: Claude Platform model overview, retrieved 2026-10-10)
If you already run Claude Code, start by putting Haiku behind a narrow subagent role and measure cost per completed task before widening it. For the primary model migration, use our Claude Opus 5 setup guide or Claude Sonnet 5 migration guide. For team defaults, the Claude Code daily-driver guide covers the surrounding CLI workflow.
Sources
- Introducing Claude Haiku 5.5 — Anthropic, October 7, 2026
- Claude Haiku 5.5 model overview — Anthropic documentation
- Claude Haiku 5.5 system card — Anthropic
- Claude models overview — Anthropic documentation
Source: Anthropic